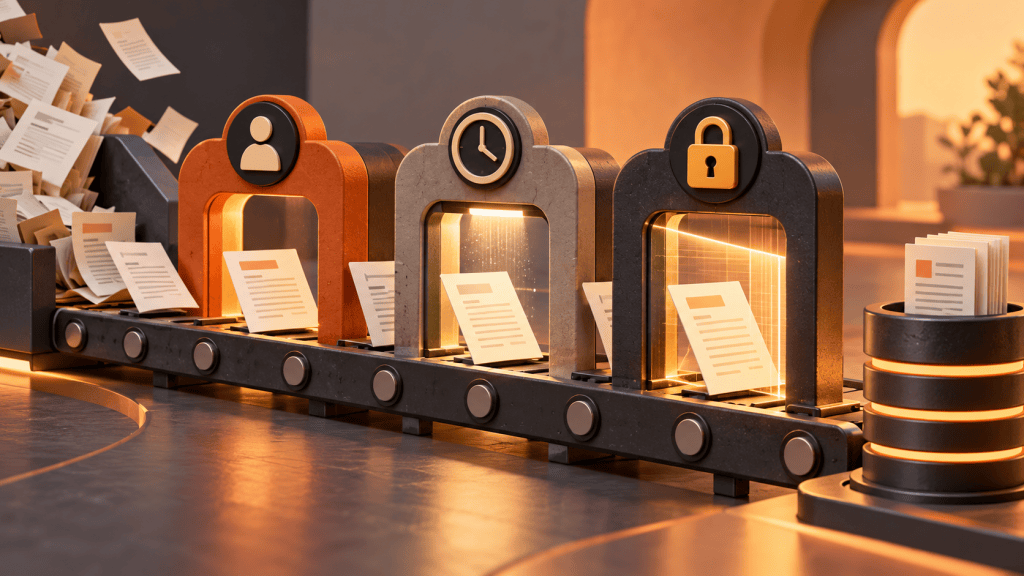
Featured image: AI-generated conceptual illustration. Sources checked 26 October 2026.
The hardest part of a knowledge assistant may happen before the model sees a question. A business has to decide which documents count, who owns them, when they stop being valid and who may read them. Without those decisions, an index can make an untidy knowledge estate easier to search without making it more trustworthy.
Before investing in retrieval tuning, inspect the information supply chain. Treat it as a maintained service: documents enter, change, expire and leave. An assistant should not be the first place an organization discovers that three departments publish different versions of the same policy.
Run a small knowledge audit
Choose one bounded subject, such as travel expenses in a hypothetical consulting firm. Gather the sources an employee would reasonably encounter: the current policy, regional addenda, onboarding slides, finance FAQs and archived announcements. Do not begin by uploading every file in the company.
For each source, record the owner, intended audience, effective date and status. Ask the owner to identify which document takes precedence when wording conflicts. If there is no owner, flag that as a business problem. A model can summarize disagreement, but it cannot create legitimate policy authority.
The OpenAI retrieval documentation describes file attributes and filtering. Those technical features can help narrow searches, but their usefulness depends on meaningful metadata. A field called current is only reliable if someone is responsible for changing it when the policy changes.
Separate freshness from upload time
A recently uploaded file can describe an old rule. An older file can remain the authoritative policy. Store dates that reflect the business meaning: publication, effective start, review due and superseded status may all differ. Avoid treating the latest upload as automatically correct.
For the travel example, a regional meal allowance might take effect next month. The assistant should distinguish a question about an expense already incurred from a question about a future trip. If the retrieval pipeline ignores effective dates, it can return the correct document for the wrong period.
Design the ingestion process to preserve those distinctions. When a source changes, identify whether the new version replaces the old one, supplements it or applies only to a different audience. Re-indexing a file is not enough if the old version remains searchable without a status marker.
Define an exit process for obsolete material
Teams often spend more effort adding documents than removing them. Specify what happens when a policy is withdrawn, an employee loses access or a document owner requests deletion. Consider the source repository, search index, generated summaries and caches separately.
The desired behavior may be to retain an archived source for authorized historical questions while excluding it from current-policy answers. That requires an explicit distinction between current use and historical retention. Do not let a cleanup operation accidentally erase records the business still needs, and do not let retention become an excuse to serve obsolete advice.
Test the exit process with a harmless sample document. Remove or restrict it, then ask the assistant questions that previously retrieved it. Inspect snippets and follow-up answers as well as direct links. This exercise reveals whether the system’s apparent deletion actually changes what users can receive.
Make permissions part of retrieval
An assistant should inherit a deliberate access model rather than flattening every connected source into one universal library. A consulting firm may have client-specific folders, confidential personnel policies and public staff guidance. Semantic similarity does not make those boundaries irrelevant.
OWASP’s vector and embedding guidance discusses unauthorized access and information leakage in retrieval systems. Use that risk as a test requirement: two users asking the same question may legitimately receive different available evidence.
Prefer permission checks before restricted content enters the model context. Hiding the final citation does not undo disclosure if the answer paraphrases the passage. Also review caches and saved conversations, where information can survive beyond the retrieval request that first exposed it.
Give the owner a useful quality report
A document owner does not need a dashboard full of embedding terminology. They need to know which questions fail, which sources conflict and which records are overdue for review. Translate retrieval errors into actions someone can take.
- Missing: users ask a recurring question with no authoritative answer.
- Conflicting: multiple active sources imply different rules.
- Stale: a source exceeds its review date or references an expired process.
- Unclear: the wording cannot support an unambiguous answer.
- Restricted: the relevant information exists but requires a different access path.
- Misclassified: metadata places a source in the wrong region, audience or period.
This report can improve the knowledge base even before an assistant is deployed. It can also prevent teams from treating every bad answer as a model issue. If employees themselves cannot determine which document applies, retrieval optimization alone is unlikely to solve the problem.
Treat external text as evidence, not authority over the agent
A maintained knowledge base can still contain text that tries to redirect an assistant. Documents, comments and imported pages are data sources, not permission to change the agent’s instructions. OWASP’s prompt-injection guidance makes clear that retrieval does not remove this class of risk.
Keep document ingestion and source approval separate from authorization to perform actions. An expense-policy paragraph should help answer an expense question; it should not grant an agent access to payroll exports or tell it where to send private records. Test that boundary using approved synthetic examples.
Launch with a manageable knowledge domain
Start with a subject whose owners, documents and access rules can be inspected. Publish the coverage boundary so users know what the assistant can answer. Expand only when the maintenance process works, not merely because the index accepts more files.
A good knowledge assistant depends on a good knowledge operation. Ownership, freshness and access are not administrative extras. They determine whether the system retrieves evidence that the user is entitled to see and the business is prepared to stand behind.
Sources and further reading
OpenAI: Retrieval. File attributes and filtering mechanisms; checked October 2026.
OWASP: Vector and Embedding Weaknesses. 2025 retrieval access-control risks; checked October 2026.
OWASP: Prompt Injection. 2025 guidance on untrusted external content and limits of RAG as a defense; checked October 2026.


Leave a Reply