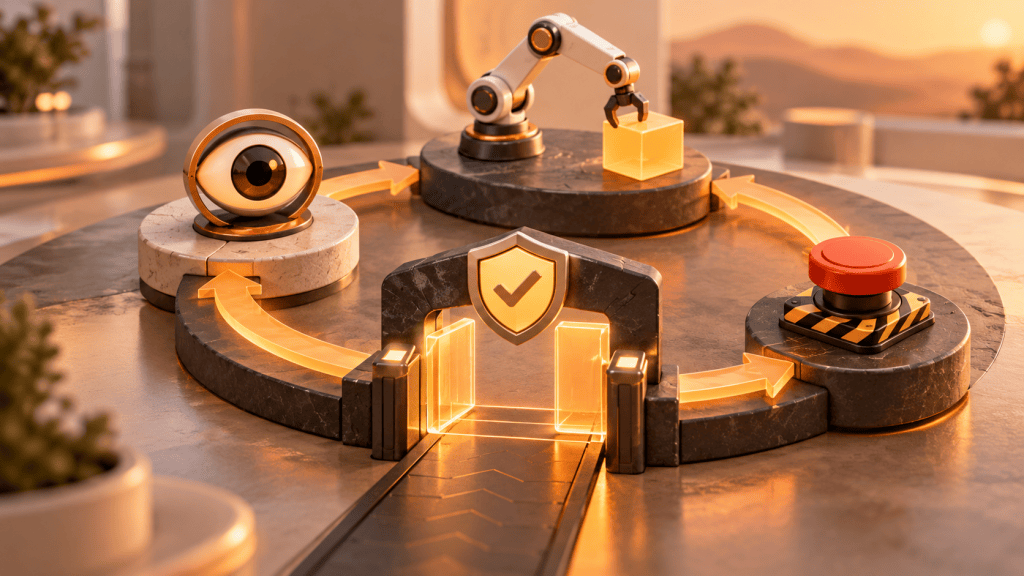
Featured image: AI-generated conceptual illustration. Sources checked 26 October 2026.
“I have updated the order” is a statement. A confirmed change in the order system is evidence. The difference matters whenever an AI agent moves beyond answering questions and begins working through tools. A business process should end because its acceptance criteria are satisfied, not because the assistant sounds finished.
A useful way to understand an agent is as a loop: inspect the current situation, choose an allowed action, observe the result and decide whether another step is necessary. The loop runs inside an application that supplies tools, checks permissions and determines what can happen next. It needs explicit ways to finish, pause and fail.
Follow one ordinary request
Imagine a fictional customer asking a distributor to correct a delivery address before an order ships. The customer provides an order number and a new address. A chat-only system could explain the change policy. A tool-using agent can potentially inspect the order, determine whether changes remain possible and prepare or execute an authorized update.
The first observation is incomplete. An order number does not by itself establish the requester’s identity, the order’s ownership or its shipping status. Those checks need to happen through the application’s trusted systems. The agent should not infer permission from a persuasive message or from the fact that a record exists.
After an authorized read, the order tool might report that the shipment is still pending. The agent now has a reason to continue. If the shipment is already dispatched, it needs a different path, perhaps explaining that the requested change is unavailable and handing the case to an employee. The business should define both outcomes in advance.
A tool request is a proposed operation
The model can select a tool and provide arguments such as an order identifier and destination address. The OpenAI function-calling documentation describes the exchange between model-generated tool requests and application-side execution. For operations leaders, the important point is that generating a request and successfully performing it are separate events.
Application code should validate the arguments, enforce access and reject an operation that violates policy. It might also require human approval. If a postcode is invalid or the order no longer permits changes, the tool should return a clear result that the agent can interpret without inventing a workaround.
This separation makes failures easier to reason about. A tool selection error means the agent asked for the wrong operation. A validation failure means the proposed inputs were unacceptable. An authorization failure means the operation was not permitted. A transport failure means the application may not know whether the request reached the destination. Each requires a different response.
Observe what actually happened
Suppose the update call times out. It is unsafe to treat that as either definite success or definite failure without further evidence. The remote system may have accepted the change before the connection broke. Repeating the write blindly could produce duplicate actions in other kinds of workflows.
A better recovery path uses an operation identifier or a fresh authorized read to determine the current state, when the integration supports that. If the result remains uncertain, the agent should report uncertainty and route the case for resolution. This is an application design pattern, not a guarantee supplied by a language model.
The Agents SDK running-agents guide documents the execution loop and its lifecycle. SDK machinery can manage repeated model and tool interactions, but business verification still belongs in the workflow. A framework cannot decide which database field is authoritative unless the application establishes that relationship.
Verification is its own step
After a successful address update, check the saved address and order status rather than relying only on the proposed arguments. If another system performs fulfillment, determine whether the change propagated to the place that actually controls shipment. “Saved in the CRM” and “used by the warehouse” may describe different outcomes.
The final message should match the evidence. If the order system confirms the change but warehouse synchronization is pending, say so. If only a request was submitted for review, do not call the address corrected. Precise status language prevents a conversational interface from hiding an incomplete business process.
Give the loop named exits
- Completed: the agreed postcondition is verified and any required artifact exists.
- Awaiting approval: a specific proposed action is ready for an authorized reviewer.
- Blocked: required information, access or a dependency is unavailable.
- Denied: policy or a reviewer disallowed the proposed action.
- Failed: an error prevents completion and the recovery path is exhausted or unsafe.
- Canceled: the user or operator stopped further work.
These statuses should be visible in the application, not merely buried in a conversation. They allow operations staff to distinguish work that needs attention from work that is finished. They also make reporting more honest: a run that stopped asking questions is not necessarily a completed customer request.
Approval creates a pause rather than a fictional success. The SDK human-in-the-loop documentation shows how gated tool calls can interrupt and resume a run. The surrounding product still needs to identify the reviewer, present the action clearly and reject stale or unauthorized approvals.
Test the uncomfortable paths
Before launch, rehearse a changing order status, an invalid address, a revoked permission, a timed-out write and a customer canceling midway through the task. Inspect both the conversation and the final system state. A convincing explanation should never compensate for an unauthorized or unverified action.
The agent loop is valuable because it can adapt. Its operating discipline comes from knowing what it observed, what it attempted and what the evidence now supports. Make those distinctions explicit and a business can give an agent useful responsibility without confusing initiative with unlimited authority.
Sources and further reading
OpenAI: Function calling. Model tool requests and application-side execution; checked October 2026.
OpenAI Agents SDK: Running agents. Agent execution lifecycle and loop documentation; checked October 2026.
OpenAI Agents SDK: Human-in-the-loop. Approval interruptions and resumption; checked October 2026.


Leave a Reply